OPTIMIZED AI INFERENCE

Serve

TALK TO AN ENGINEER

Open models optimized for your workload

Your inference workloads are growing 10x a year.
Customer expectations are growing even faster.

CarbonForge keeps you ahead. We profile your workload, then serve it on an open model configured for it. More capacity and better margins, at the quality bar you set.


Qwen 3.8-27B DATA COPILOT

Qwen3.8-27B · FP8

−50% $/M tokens

measured vs official vLLM recipe · same latency target

GPU 8×H100 Stack vLLM

Qwen 3.8-27B VOICE AGENT

Qwen3.8-27B · FP8

×3.7 lower latency

measured vs official vLLM recipe · same spend

GPU 8×H100 Stack vLLM

qwen-black CODING AGENT

Qwen3.8-27B · FP8

×4.5 more throughput

measured vs official vLLM recipe · at the accuracy bar you set

GPU 8×H100 Stack vLLM

Same API calls, same quality bar. Only where it runs changes.

Configured for your workload, not for the average one

Every open model ships with a default config. A support agent, a coding agent and a data copilot do not need the same one, and the right one changes with your traffic. We profile your real traffic, search for the recipe that fits it, lock the result in, and run the search again when your traffic or the model changes.

Chat Agent
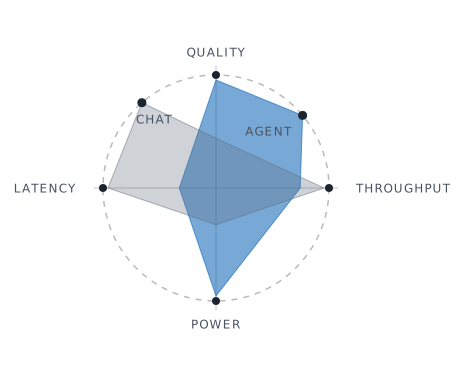
CarbonForge Inference Optimization
Frontier Model
DIY Open Model
CarbonForge
Runs without an ML infra team
icon-check
icon-close-2
icon-check
Keeps your code and prompts unchanged
icon-check
icon-close-2
icon-check
Never compromises quality for speed
icon-check
?
icon-check
Picks the model that fits your workload
icon-close-2
icon-check
icon-check
Optimizes for your real traffic
icon-close-2
icon-close-2
icon-check
Adapts as your traffic shifts
icon-close-2
icon-close-2
icon-check
Time to deploy
Already running
Months
24 hours
What it costs
Rises with your traffic
Headcount and GPUs
Falls as we optimize

Self-hosted means running an open model yourself, on rented or owned GPUs.
Every published figure names its GPU, its model, its precision and its vLLM version.


Only the endpoint URL changes

We profile your traffic, search for the serving recipe that fits it, and run your workload on an open model, on an endpoint we host for you. You point your client at a new URL. Your prompts, your calls and your quality bar stay as they are.

Programs and platforms we work with

Subscribe to updates

New optimized containers, benchmark results, and learnings from tuning inference in production. Email about once a month, opt out any time.