 DATA COPILOT
Qwen3.8-27B · FP8
−50% $/M tokens
measured vs official vLLM recipe · same latency target
GPU 8×H100
Stack vLLM

 DATA COPILOT
−50% $/M tokens
measured vs official vLLM recipe · same latency target
GPU 8×H100
Stack vLLM
VOICE AGENT
×3.7 lower latency
measured vs official vLLM recipe · same spend
GPU 8×H100
Stack vLLM
CODING AGENT
×4.5 more throughput
measured vs official vLLM recipe · at the accuracy bar you set
GPU 8×H100
Stack vLLM
Same API calls, same quality bar. Only where it runs changes.
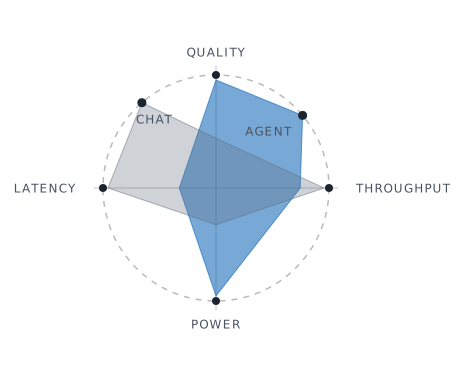
Every open model ships with a default config. A support agent, a coding agent and a data copilot do not need the same one, and the right one changes with your traffic. We profile your real traffic, search for the recipe that fits it, lock the result in, and run the search again when your traffic or the model changes.
Chat Agent