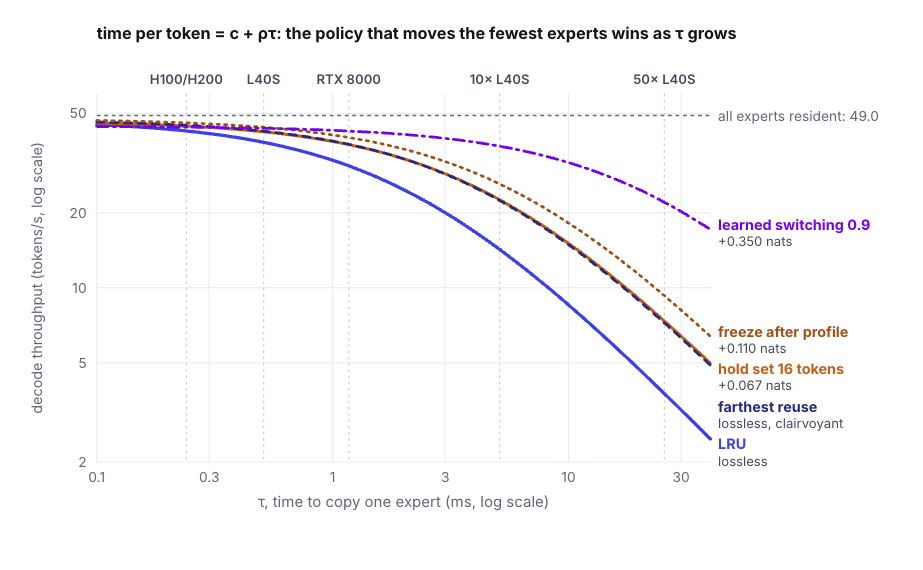
Paging experts: in offloaded MoE serving, the cheap win is eviction, not routing
A mixture-of-experts (MoE) model is cheap to run per token and expensive to hold in memory. When its experts do not all fit on the GPU, a serving system keeps s …

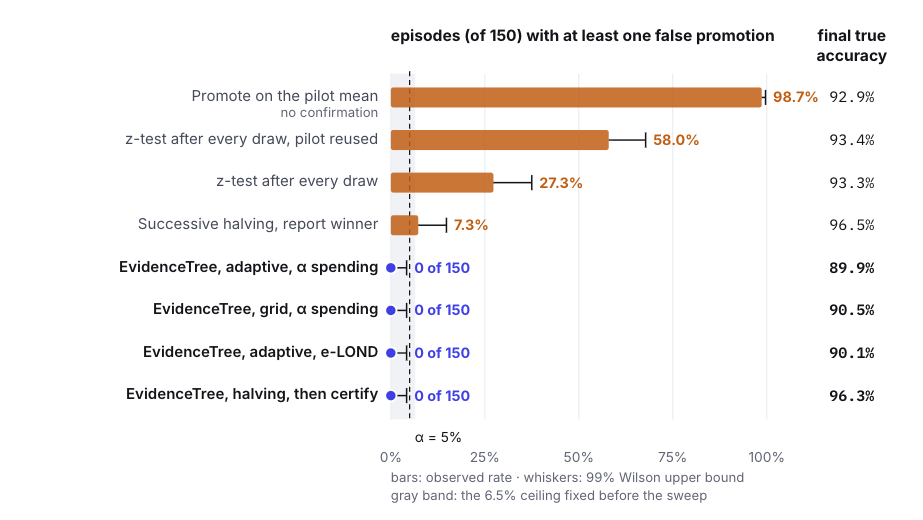
Testing by betting: how we keep discovery agents from fooling themselves
An agent that chooses its own experiments can confirm a false finding in three ways: by checking the result after every new data point, by testing many claims a …
Food for thought: how the 20W brain compares to a GPU. Measured in poutine.
The human brain is amazing for many reasons, and one of the biggest is its efficiency. It runs on 20 watts.

First Fable, then NVIDIA and HuggingFace. Is it time for Owned Intelligence?
It seems that we are at an inflection point, perhaps even a tipping point. Companies are re-evaluating their AI strategy and asking an important question: is it …
GPU waste, tokens per dollar, and the impact on inference businesses
The cost of AI is in the spotlight, and every part of the AI industry has at least some focus on improving efficiency to reduce that cost.Model builders, improv …
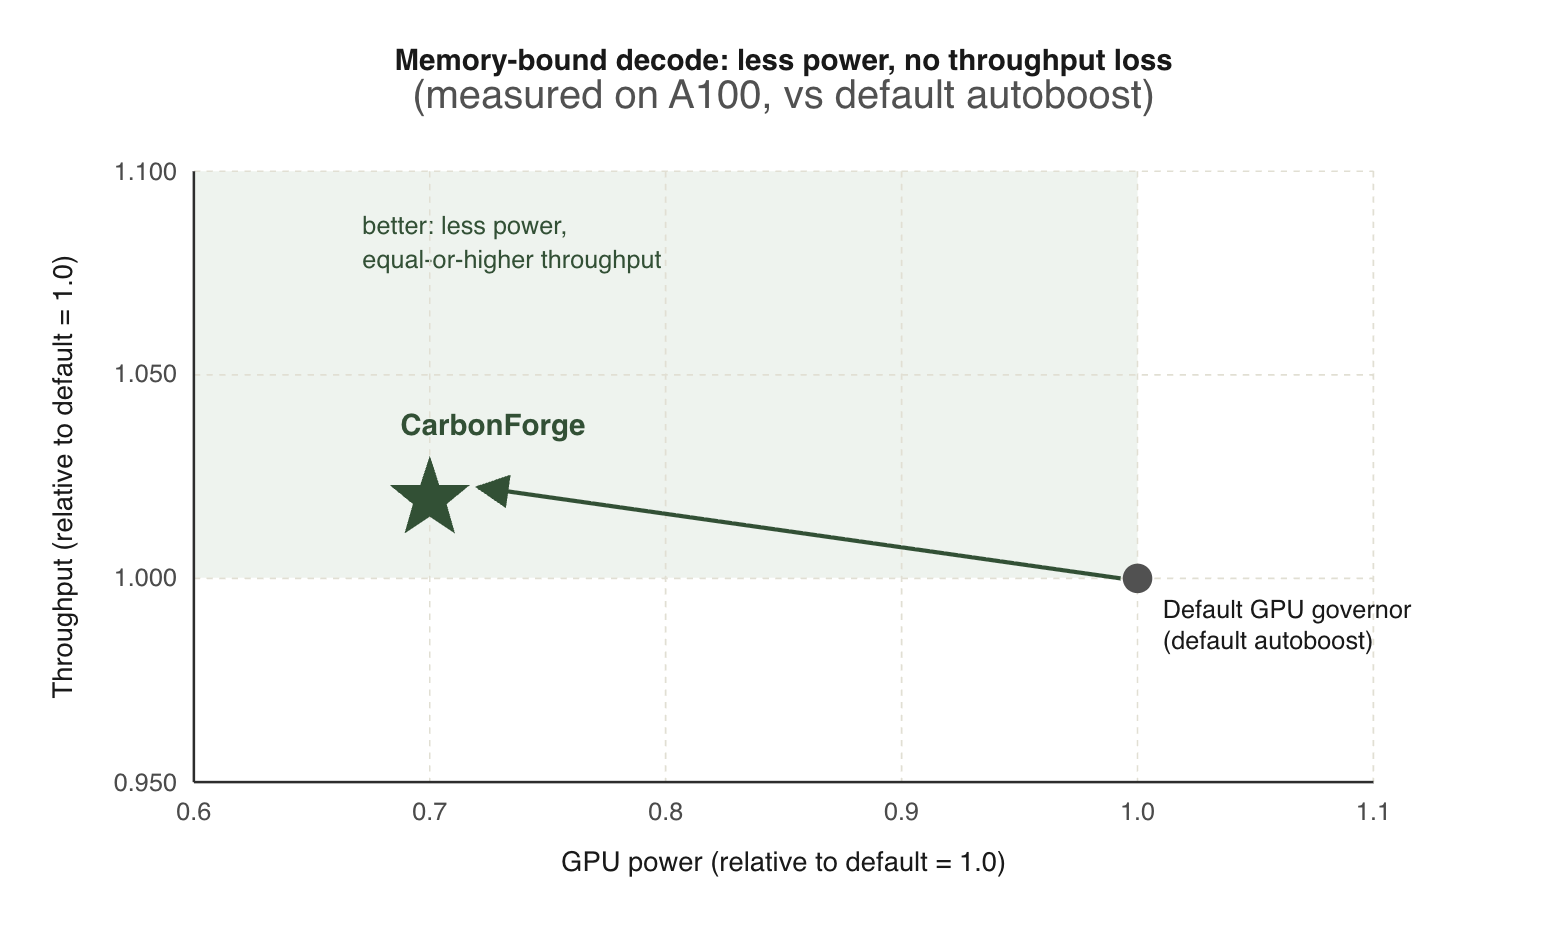
Adaptive SM clocking for energy-efficient LLM serving
LLM serving is moving from occasional jobs to persistent service infrastructure. At that scale, GPU power is no longer a background detail. It sets thermal limi …